Build apps and fix code with ad-funded coding access; check current model and session limits.
Provider-checked pricing
AI TOOL DETAILS
Use the documented local Ollama endpoint for chat and retrieval without buying an API plan.
The listed option is free to use. Hosting or model usage may still cost money.
The Apache-2.0 app can be run without a software subscription. A local model download and suitable device are required; any external APIs are optional and have their own charges and terms. No model weights are bundled. A compatible local model such as Ollama's qwen2.5-coder:7b is listed under Apache-2.0 at 4.7GB; confirm model compatibility and its license separately. Hardware, model download/storage, and electricity remain user costs. Optional hosted or API inference may be billed.
Provider pricing checked 1 Nov 2026.
The local application path needs no per-request API. Model weights and capable hardware are separate; optional remote model connections may cost money.
No one-line command has been verified for LocalLLMMind; follow its official installation instructions instead of guessing a Docker image or installer.
LocalLLMMind provider setup documentationRead the repository for the license, installation steps, and operating costs.
Source repositoryView the full software profileRead a practical guide before choosing a plan or setting up a workflow.
How to use an AI coding tool and check its workThis preference stays on your device. It does not change public rankings.
Build apps and fix code with ad-funded coding access; check current model and session limits.
Provider-checked pricing

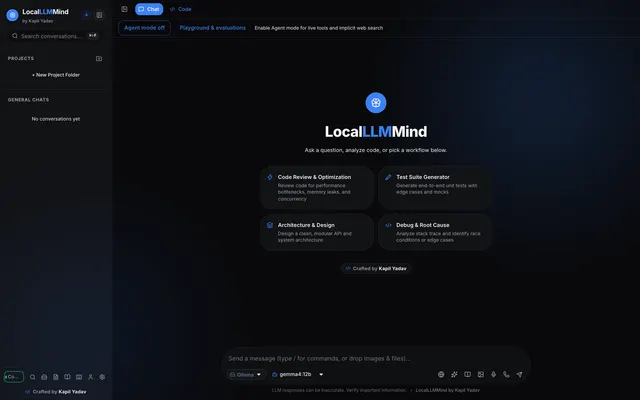
A browser workspace for local chat, web-search results and your own SearXNG.
Provider-checked pricing
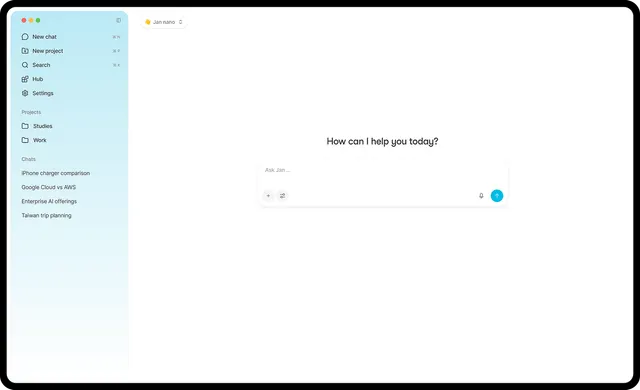
Desktop chat with downloaded models; no paid API key needed for local conversations.
Provider-checked pricing
Allow Google Analytics to measure page visits and basic device information using cookies? Your searches and form entries are excluded. You can change this choice at any time. Privacy details.