Use a compatible local llama.cpp model for coding tasks without a paid API call.
Free local application · model/hardware costs separate
The MIT terminal agent can use local llama.cpp inference. The model is not bundled: choose compatible weights and review their license separately. Cloud providers, including examples in the project demo, can add usage charges. No weights are bundled. The official Ollama qwen2.5-coder:7b listing states Apache-2.0 and 4.7GB; verify compatibility and model licensing separately. Local hardware, storage, download, and electricity still have costs. Optional remote inference can be billed.
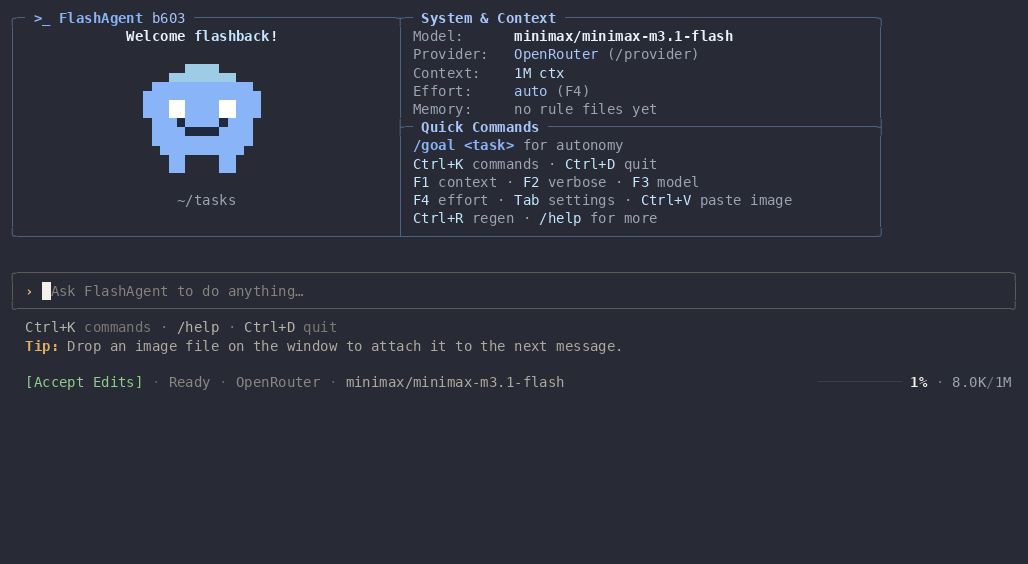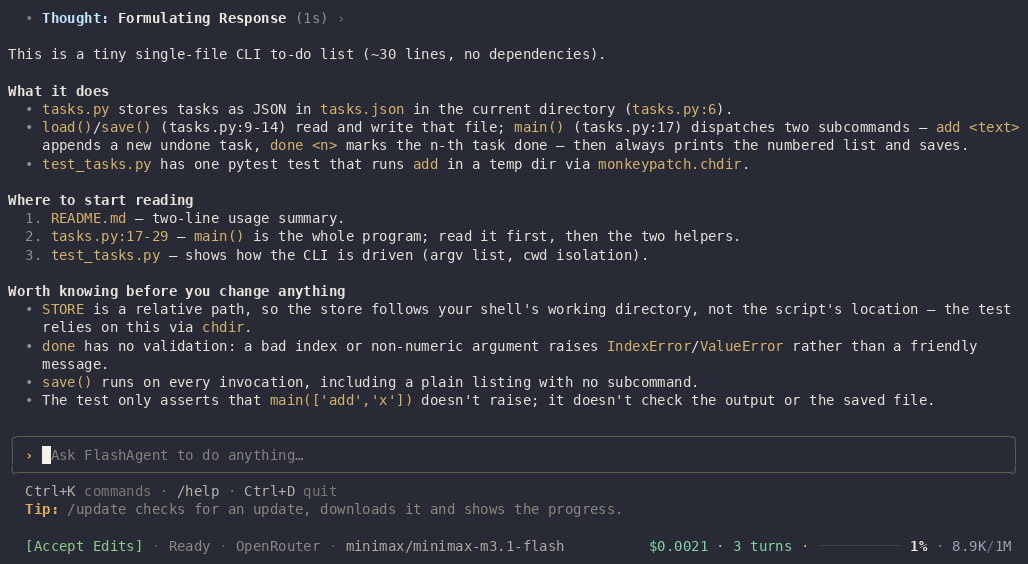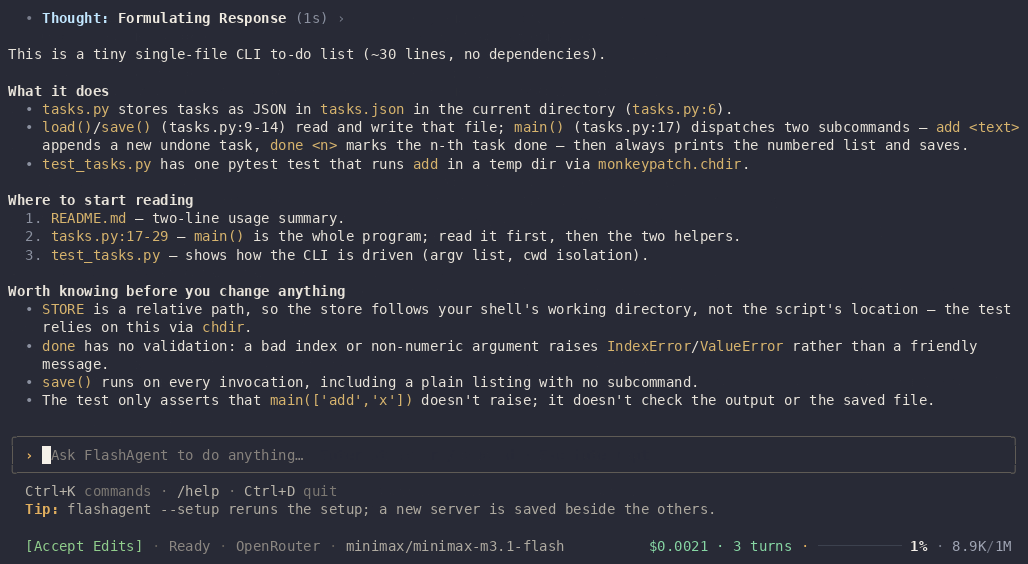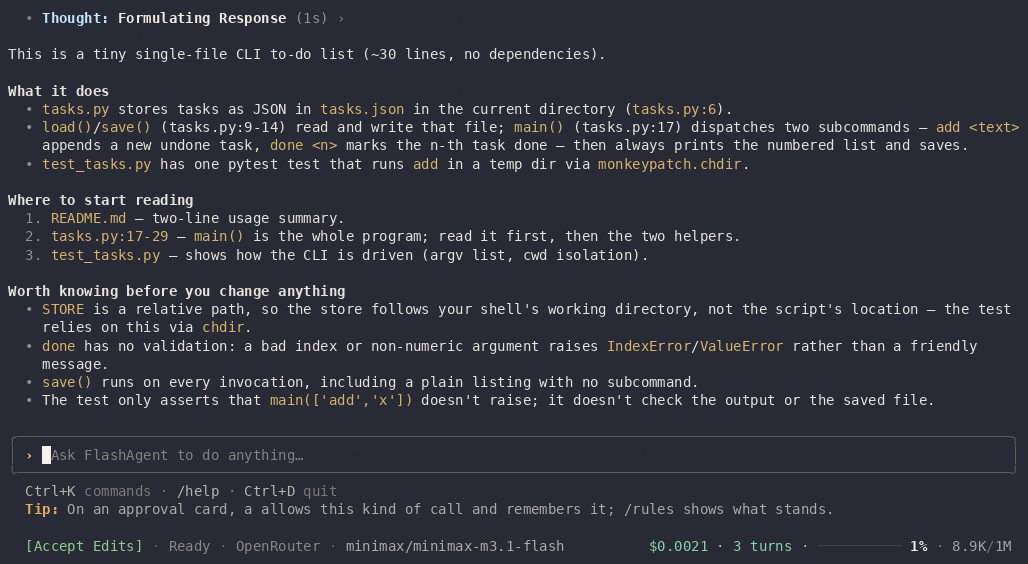
FlashAgent · Project terminal demo GIF; the shown OpenRouter/model setup may involve separate API charges.Product image: flashback7766 · MIT · Original image; layout scaled to fit. Project terminal demo GIF; the shown OpenRouter/model setup may involve separate API charges. Full notice.Logo: flashback7766 · MIT · Original image; layout scaled to fit. Provider asset identifies flashagent; no endorsement is implied. Full notice.
About FlashAgent
A terminal coding agent with a local llama.cpp route as well as optional hosted providers. Local setup reduces dependence on per-call API pricing, with hardware and model tradeoffs. A self-hosting option is recorded for this project. Review the official deployment instructions and maintenance requirements before running it yourself.
Release status
Official README and root license checked against this revision on 2026-11-01. Local model and provider costs are recorded separately; AltStack did not execute the project or its installers.
Install on your computer · Instructions checked 2026-11-01
Read the official README for the current CLI requirements and supported local inference backend.
Install FlashAgent using only the official repository instructions.
Start the documented local llama.cpp-compatible inference service and select a model supported by that service.
Try a small disposable repository before allowing the agent to read or modify important project files.
Local inference avoids a paid model API when configured as documented. Model weights, hardware, disk space, and electricity are separate.
Self-hosting & quickstart specs
License
MIT
Deployment
Local desktop application
Free edition / costs
Free local application · model/hardware costs separate. The MIT terminal agent can use local llama.cpp inference. The model is not bundled: choose compatible weights and review their license separately. Cloud providers, including examples in the project demo, can add usage charges. No weights are bundled. The official Ollama qwen2.5-coder:7b listing states Apache-2.0 and 4.7GB; verify compatibility and model licensing separately. Local hardware, storage, download, and electricity still have costs. Optional remote inference can be billed. Pricing evidence.
Devices / hardware
Local inference avoids a paid model API when configured as documented. Model weights, hardware, disk space, and electricity are separate.
No one-line command has been verified for FlashAgent; follow its official installation instructions instead of guessing a Docker image or installer.
OpenCode can be used without a Go subscription. Optional Go is USD 10/month and Go Plus USD 40/month, with model-specific usage limits. Local models use your hardware; connected provider APIs and subscriptions bill separately. Promotional free models are limited-time offers.
Minimal terminal coding agent you can fully customize.
Official README supplies the installable Pi harness under MIT and instructs users to connect their own provider subscription or API key. The free harness does not include model usage or provider subscription fees.
Autonomous coding agents that complete real engineering tasks.
Official pricing lists MIT Agent Canvas free to self-host using own LLM key, Teams $499/month for up to 10 users with extra seats $50/month, and custom Enterprise. Provider tokens and managed cloud are separate.
Use an AI coding agent in an editor or terminal, with an optional local model.
The Apache-2.0 Cline VS Code extension and CLI have no software license charge. Use local Ollama models without a paid API key or per-request model charge, on your own hardware. Cline usage-billing, ClinePass subscriptions and external cloud model providers are optional paid routes with their own terms. The current repository says its JetBrains plugin is not open sourced. This review establishes the local client route, not unlimited hosted inference.
Coding agent that runs on local and open-weight models.
The Open Interpreter repository edition is available under Apache-2.0 with documented installation or build instructions and no required source-license subscription. Your server, storage, backups and administration remain your costs. External model/API usage is billed by its provider; no model allowance is included. This check covers that source edition; managed services, premium extensions and commercial relicensing, if offered, are not included or price-verified.
General-purpose AI agent for code, workflows, and more.
The Apache-2.0 agent has a documented local model/provider route with no required agent source-license subscription. You provide hardware, storage, power and separately licensed models. Optional hosted inference, credits and cloud accounts have separate charges and limits.
Allow Google Analytics to measure page visits and basic device information using cookies? Your searches and form entries are excluded. You can change this choice at any time. Privacy details.