Free local application · model/hardware costs separate
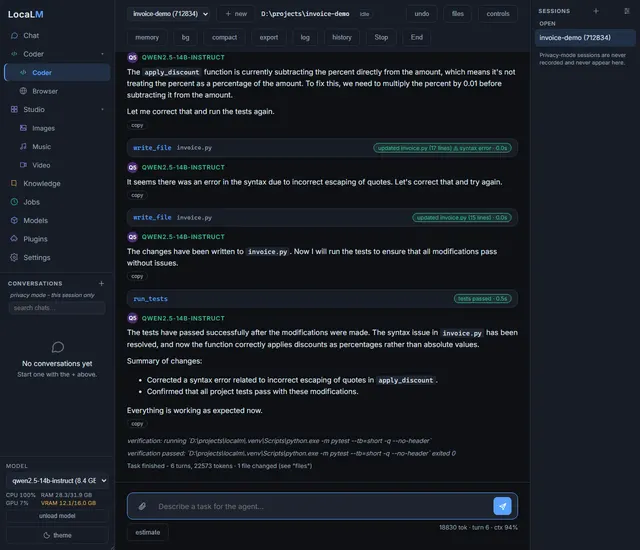
Offline chat and coding can run on the user’s machine without a hosted AI subscription.
The AGPL application is free to run. Local inference requires separately downloaded model weights and capable hardware; optional cloud providers or plugins can have their own prices and terms. Telemetry and data-location details should be reviewed in the project documentation. No weights are bundled. The official Ollama qwen2.5-coder:7b listing states Apache-2.0 and 4.7GB; verify compatibility and model licensing separately. Local hardware, storage, download, and electricity still have costs. Optional remote inference can be billed.
7stars—30 daysAGPL-3.0-or-later
USE INSTEAD OF